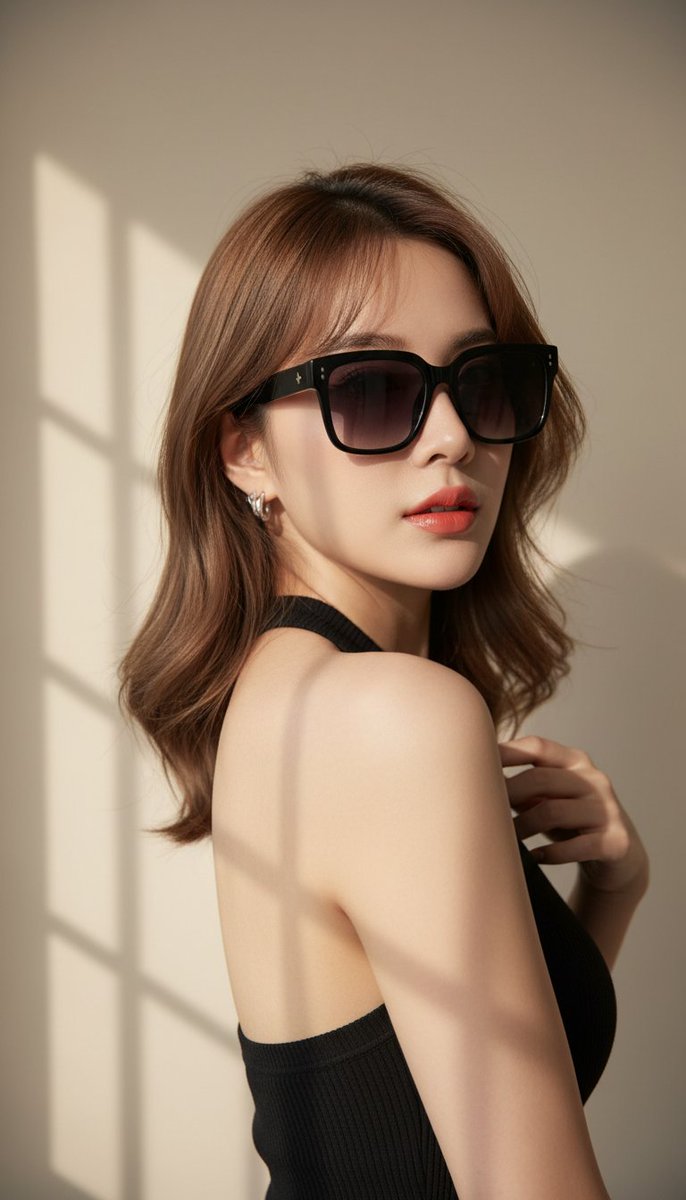
In one sentence: This breaks down a well-crafted window-light portrait prompt, focusing on how it uses slot syntax to upgrade a one-off prompt into a reusable template, and how it handles the light chain and material callbacks; suited for those who already know basic portrait prompting and want to start building their own template library.
Field Table
| Field | Value |
|---|---|
| model | General image model. Rationale: the original prompt contains no model-specific syntax or parameters; the source library overall targets Nano Banana Pro, but the prompt text is cross-model usable |
| duration | Not applicable (single-frame still) |
| aspect | 1:1 |
| seed and reproducibility | Not recorded; unverified — the author has published the final image, this library has not re-run it |
| final image link | Embedded preview on page, see card above and original post |
| estimated cost | To be estimated (per official pricing, using cost calculator) |
| author and original link | YouMind-OpenLab · https://github.com/YouMind-OpenLab/awesome-nano-banana-pro-prompts |
License and attribution: This prompt comes from YouMind-OpenLab’s open-source prompt library; the repository README marks CC BY 4.0 (GitHub API returns NOASSERTION). This library retains the author and original link per attribution requirements; the actual license is governed by the repository LICENSE.
prompt_zh
Reproduced verbatim (attribution + original link complete, see field table):
一张逼真的特写肖像,主角为一名 {argument name=“subject” default=“年轻东亚女性”},20 岁出头,留着浅棕色齐肩长发,配有柔和的刘海和修饰脸型的微卷。她佩戴着 {argument name=“accessory” default=“超大黑色长方形太阳镜”},镜片带有深色渐变效果,配有厚实的黑色镜框。妆容自然精致:眉形柔和清晰,腮红淡雅,珊瑚蜜桃色唇釉。她戴着小巧的银色双环耳饰。身穿一件黑色修身罗纹针织挂脖上衣,高圆领设计,露出双肩和上胸部。姿势为柔和的自拍视角:身体微微侧转,一只手轻搭在对侧肩膀附近,回眸看向镜头,表情沉稳自信。背景为一面 {argument name=“background” default=“简约浅米色墙壁”},柔和的自然窗光在墙面和她的脸上投射出清晰的几何窗影。柔和的定向阳光在她的头发、皮肤和罗纹上衣的纹理上形成了细腻的高光。高细节写实摄影风格,自然的皮肤质感,柔和的背景虚化,优雅现代的美学,高分辨率。
Breakdown
5 Things It Does Right
1. It uses Raycast fragment syntax to explicitly mark the replaceable parts. A construct like {argument name="subject" default="年轻东亚女性"} isn’t for the model — it’s for humans and editors: pasting it pops up a fill-in box, and leaving it blank falls back to the default. What’s truly worth learning is the choice of slots — subject, accessory, and background map exactly to the three most frequently changed dimensions (swap person, swap object, swap scene), while everything else stays fixed. A single prompt thus evolves from “a one-off sentence” into “a template that can run twenty times,” and it doesn’t depend on any model capability — swapping in {{subject}}, [主体], or any other placeholder syntax works just as well.
2. The light is written as a three-part chain — “source → landing point → result” — rather than just one adjective. The source is “柔和的自然窗光” (soft natural window light), the landing point is “在墙面和她的脸上投射出清晰的几何窗影” (casting clear geometric window shadows on the wall and her face), and the result is “在她的头发、皮肤和罗纹上衣的纹理上形成了细腻的高光” (forming delicate highlights on her hair, skin, and the texture of the ribbed top). Most people stop after the first part, and models interpret a word like “window light” very broadly; once you add the landing point (where the window shadow falls, and what shape it takes) and the result (which surfaces the highlights land on), what becomes controllable shifts from “mood and brightness” to “specific elements you can point to in the frame.” Note the phrase “几何窗影” (geometric window shadow) — it simultaneously conveys hardness (crisp edges), direction (has orientation), and pattern (grid-like); one word does three jobs. Cross-reference the library’s “Describing Light and Atmosphere” entry.
3. Makeup is described with anchor points — only three spots get attention. “眉形柔和清晰,腮红淡雅,珊瑚蜜桃色唇釉” (soft, defined brows; subtle blush; coral-peach lip gloss) — one line each for brows, cheeks, and lips, then done. This is restraint: the more makeup detail you write, the less the model will implement it item by item, and it will instead crowd out weight from other parts. The choice of these three spots is also defensible — they’re the largest areas in a close-up portrait and the three that most affect overall color tone. Only the lip gloss gets a specific color (coral-peach); the other two get only degree words, effectively spending the “precision control” budget on the single most valuable spot.
4. Pose is written as relationships between body parts, not adjectives. “身体微微侧转,一只手轻搭在对侧肩膀附近,回眸看向镜头” (body slightly turned, one hand resting near the opposite shoulder, looking back at the camera) — three clauses lock down torso orientation, arm position, and head/neck/eye direction respectively. Compare this to the common “elegant, confident pose,” which carries almost no information. Especially notable is the phrasing “对侧肩膀” (opposite shoulder): it uses a relative relationship rather than absolute left/right, which both establishes the arm crossing in front of the body and avoids fighting over a left-right distinction the model can’t reliably make anyway. The earlier phrase “柔和的自拍视角” (soft selfie angle) also specifies camera height and distance in one go, incidentally explaining why this pose works.
5. Material words are reused twice, creating cross-constraints. “黑色修身罗纹针织挂脖上衣” (black fitted ribbed knit halter top) appears once in the clothing section, then gets recycled in the lighting section as “罗纹上衣的纹理上的高光” (highlights on the texture of the ribbed top). When the same object is mentioned in two different positions in a prompt, the model finds it harder to ignore; moreover, the second mention is framed from the light’s perspective, effectively requiring the “ribbed” structure to actually render in a lit form rather than as a vague black top. This arrangement — “declare the object first, then recycle it in the lighting section” — is one of the few structural techniques in long prompts that genuinely improves detail delivery rates.
Where It Could Improve
1. Slots are only half-parameterized — swap the subject and the template becomes self-contradictory. The subject slot can be filled with anyone, but what follows it — “20 岁出头,留着浅棕色齐肩长发” (early 20s, light brown shoulder-length hair), “妆容自然精致…珊瑚蜜桃色唇釉” (natural refined makeup… coral-peach lip gloss) — is hardcoded. Change subject to “中年男性” (middle-aged man) and all those descriptions remain, sending the model a set of conflicting instructions. When writing your own version, slot boundaries should cut across semantically complete chunks — either make the subject slot cover the entire appearance description from age to makeup, or split hair and makeup into their own slots; don’t let downstream sentences depend on a slot’s default value.
2. No aspect ratio or framing declaration. The entire text only hints at shot size with “特写肖像” (close-up portrait); aspect ratio is never mentioned. The 1:1 on the preview card is a property of the final image, not something the prompt specified. Across 1:1, 3:4, and 2:3, the proportion of “露出双肩和上胸部” (shoulders and upper chest exposed) plus “几何窗影” (geometric window shadows) that can fit in frame differs completely — the window shadow might even get cropped out by half. Adding one upfront sentence on aspect ratio and framing range (e.g., “square frame, chest-up shot, subject slightly left of center”) costs almost nothing. See “Declaring Aspect Ratio / Frame Rate / Duration Upfront.”
3. No negative list. The frequent failure modes for this type of prompt are predictable: the photographer’s reflection appearing in the sunglass lenses, the halter top being rendered as a spaghetti-strap top or tube top, window shadows turning into regular tiled fake grids, or incorrect finger counts. All of these belong in an AVOID section — they’re highly targeted and won’t accidentally harm the subject description. See “Writing Negative Lists (AVOID Sections).”
4. The closing quality words are pure filler. Of the five phrases — “高细节写实摄影风格,自然的皮肤质感,柔和的背景虚化,优雅现代的美学,高分辨率” (high-detail photorealistic style, natural skin texture, soft background blur, elegant modern aesthetic, high resolution) — only “柔和的背景虚化” (soft background blur) carries actionable information (it’s really talking about aperture); the other four are largely ineffective on modern models — “高分辨率” (high resolution) won’t change output dimensions, and “优雅现代的美学” (elegant modern aesthetic) has no decidable referent. The end of a prompt is a high-weight position, and giving it to these words is wasteful. The same length spent on focal length and camera position (e.g., “85mm medium telephoto, at eye level, slight downward angle”) carries far more information density. Cross-reference “The Visual Language of Focal Lengths” and “The Three Elements of Depth of Field.”
All judgments above are based on the prompt text alone, without re-running generation for verification — marked unverified.
Further Reading
- “Describing Light and Atmosphere”
- “Writing Negative Lists (AVOID Sections)”
- “Declaring Aspect Ratio / Frame Rate / Duration Upfront”